中间层优先 / Middle layer first
先有干净 Markdown,再谈智能。 / Clean Markdown before intelligence.
方案 · 数据工作流 / PLAYBOOK · DATA WORKFLOW
教学素材 PDF → Markdown 的 AI 前置工作流 / Teaching-material PDF → Markdown, the AI prep pipeline
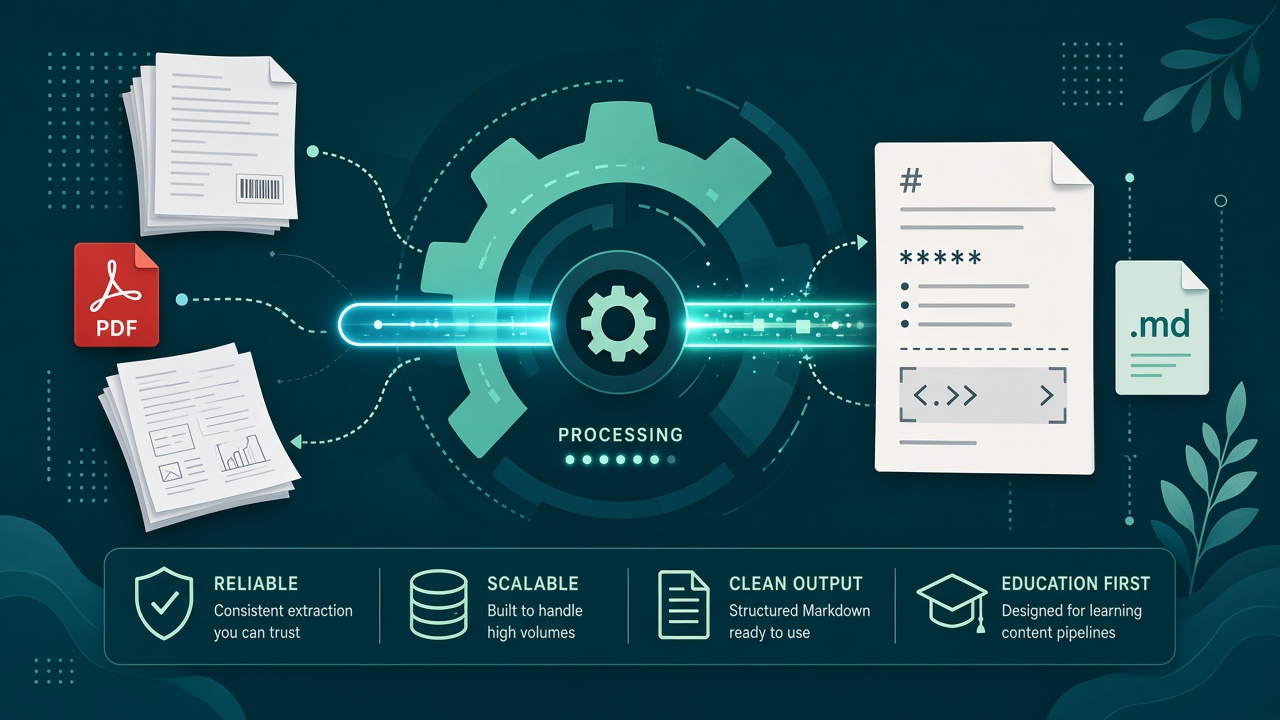
素材管线是一套教学素材数据清洗工作流:输入可以是扫描件、带图 PDF 或长截图;输出是结构清楚、公式与插图可引用的 Markdown。它不是终点产品,而是 AI 处理之前必须做对的前置工序——没有这一步,后面的阅读器、题库和备课都会在脏数据上翻车。公开介绍只讲流程与能力,不展示具体素材原文。 / Material Pipeline is a teaching-material cleaning workflow: scans, illustrated PDFs or long screenshots in; structured Markdown with usable formulae and figure refs out. It is not the end product—it is the prep step AI work cannot skip. Without it, readers, banks and lesson tools fail on dirty data. The public page describes the flow, not source material text.
问题 / THE PROBLEM
教学素材常常是扫描糊图、乱层 PDF 或拼接截图。直接丢给 AI,结构碎、公式坏、图对不上。后面无论做阅读器还是出题,都会在脏数据上返工。 / Teaching materials often arrive as blurry scans, messy PDFs or stitched screenshots. Fed raw to AI, structure breaks, formulae die and figures misalign. Readers and question tools then rework dirty data forever.
理念 / RATIONALE
理念来源 / Source · 本产品提出 · Material Pipeline(AI 前置数据卫生)
智能功能建立在可信中间层上。Markdown 是人和模型都能读的共同格式:先清洗、再结构化、再交给下游。管线可换素材包,不绑死某一套内容宣传。 / Smart features need a trustworthy middle layer. Markdown is the shared format for humans and models: clean, structure, then hand downstream. Packs swap; the page does not sell one content corpus.
先有干净 Markdown,再谈智能。 / Clean Markdown before intelligence.
同一套步骤可对下一批素材再跑。 / Same steps rerun on the next batch.
阅读、题库、备课都吃同一出口。 / Readers, banks and prep share one output.
操作 / HOW IT RUNS
素材入队 → 识别与版式整理 → 结构校验 → 导出 Markdown(含图注与元信息)。 / Queue materials → recognise and fix layout → validate structure → export Markdown with figures and metadata.
PDF、扫描件或截图进入清洗队列。 / PDFs, scans or screenshots enter the queue.
文字、公式、插图位置对齐到可读结构。 / Text, formulae and figures align into readable structure.
高质量 Markdown 进入 AI 或课堂产品。 / High-quality Markdown feeds AI or class products.
进度 / WHERE IT IS NOW
管线已在多批教学素材上跑通,作为后续产品的前置工序持续使用。公开站只介绍方案。 / The pipeline has cleaned multiple teaching-material batches and stays the prep step for later products. Public site = playbook only.
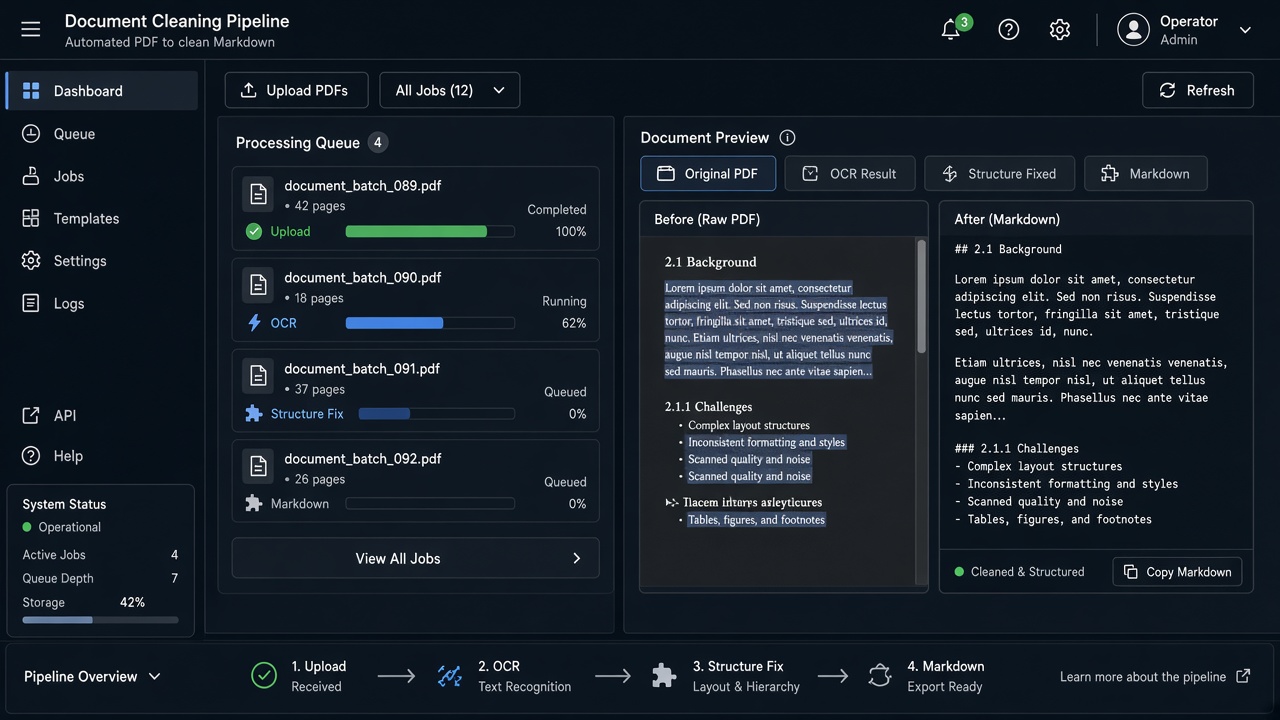
我把识别、版式整理、校验与导出收成可重复跑的管线,让教学素材能稳定进入后续 AI 与课堂产品。 / I turned recognition, layout clean-up, checks and export into a repeatable pipeline so materials enter later AI and class products cleanly.
脏数据不进模型,先过管线。 / Dirty data does not hit the model—pipeline first.
公开介绍工作流能力,不展示素材原文。 / Public copy sells the workflow, not source text.
下一批教学素材用同一套步骤。 / Next material packs reuse the same steps.